
Databricks Integration Overview
Ataccama ONE connects to Databricks through a JDBC connection to your Databricks SQL warehouse. With SQL pushdown processing enabled on the connection, profiling and DQ evaluation run directly in Databricks, with no additional licenses or operational storage required, and processing scales with your SQL warehouse. As such, we recommend using it for both Azure Databricks and Databricks on AWS.
Ataccama ONE also supports a legacy Spark processing integration, which runs Ataccama’s Spark processing engine on Databricks clusters. In addition to existing deployments that already rely on it, it is best suited for data processing plans that can’t run in SQL pushdown. For new deployments, use the JDBC connection with SQL pushdown processing.
Supported Databricks runtime versions
ONE supports the following Databricks runtime versions:
-
11.3 LTS
-
12.2 LTS
-
13.3 LTS
-
14.3 LTS
-
15.4 LTS
Databricks JDBC connection
The JDBC connection provides the same functionality as other database connections in ONE, letting you:
-
Browse and explore Databricks tables and metadata.
-
Import table schemas and metadata into ONE.
-
Run profiling and DQ evaluation, either on Ataccama Data Processing Engines (DPEs) or directly in Databricks with SQL pushdown processing.
-
Write data to Databricks tables, for example, when exporting invalid records.
No additional processing license is required.
Architecture
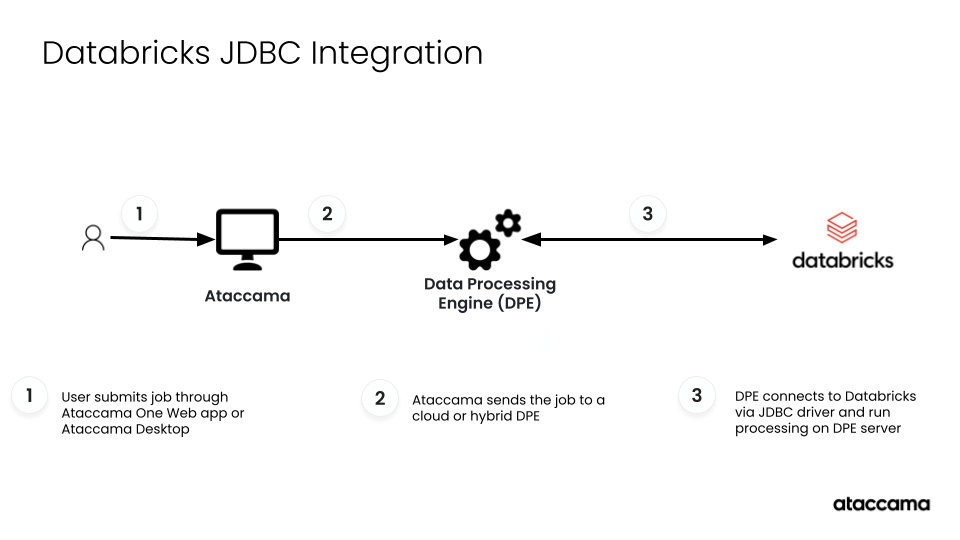
The JDBC integration requires a single connection: a standard JDBC connection from DPE to your Databricks SQL warehouse, used for all database operations. No operational storage and no REST API connection are needed.
Authentication options
-
Azure Databricks: Personal Access Token (PAT) or Entra ID Service Principal.
-
Databricks on AWS: Personal Access Token (PAT) or OAuth M2M Service Principal.
Unity Catalog
Unity Catalog is supported as an optional enhancement on both Azure and AWS.
-
JDBC connections point to the legacy metastore by default, not the Unity Catalog. You can specify a maximum of one catalog using
ConnCatalog=<name>. -
When using an all-purpose cluster, it must be a single-user cluster owned by the service principal you’re authenticating as.
To set up the connection, see Databricks JDBC.
Next steps
-
Recommended: set up a Databricks JDBC connection and enable SQL pushdown processing.
-
Existing Spark deployments: Databricks Spark Processing Integration.
Was this page useful?