
BigQuery Connection
This article describes how to connect to BigQuery.
If the BigQuery driver is not configured in your environment, refer to Data Sources Configuration.
Create a source
To connect to BigQuery:
-
Navigate to Data Catalog > Sources.
-
Select Create.
-
Provide the following:
-
Name: The source name.
-
Description: A description of the source.
-
Deployment (Optional): Choose the deployment type.
You can add new values if needed. See Lists of Values.
-
Stewardship: The source owner and roles. For more information, see Stewardship.
-
| Alternatively, add a connection to an existing data source. See Connect to a Source. |
Add a connection
-
Select Add Connection.
-
In Select connection type, choose Relational Database > BigQuery.
-
Provide the following:
-
Name: A meaningful name for your connection. This is used to indicate the location of catalog items.
-
Description (Optional): A short description of the connection.
-
Dpe label (Optional): Assign the processing of a data source to a particular data processing engine (DPE) by entering the DPE label assigned to the engine. For more information, see DPM and DPE Configuration in DPM Admin Console.
-
Override catalog item name: Select this option if you want metadata imports to overwrite the names of existing catalog items with the latest names from the data source.
If the option is not selected, catalog item names you set in ONE are preserved when metadata is reimported. See Edit catalog item metadata.
-
JDBC: A JDBC connection string pointing to the IP address or the URL where the data source can be reached.
The format of your connection string required depends on your chosen authentication method. See Google service account key JDBC and OAuth Google user JDBC respectively.
-
-
In the Pushdown processing section, optionally enable pushdown processing to run profiling and DQ evaluation directly in BigQuery. See Pushdown processing.
-
In Additional settings:
-
Select Enable exporting and loading of data if you want to export data from this connection and use it in ONE Data or outside of ONE.
If you want to export data to this source, you also need to configure write credentials. See Connection credentials.
Consider the security and privacy risks of allowing the export of data to other locations. -
Select Process semi-structured columns as JSON if you want columns with semi-structured BigQuery data types (
JSON,ARRAY,STRUCT) to be processed as JSON attributes. This lets you apply JSON-specific data quality rules to these columns.Leave this option clear (default) to process semi-structured columns as
STRING. The setting is applied during metadata import, so if you change it for an existing connection, run the metadata import again for the change to take effect on already imported catalog items.JSON attributes are excluded from profiling and can’t be exported.
-
Pushdown processing
Pushdown processing lets you run profiling and DQ evaluation directly in BigQuery instead of on Ataccama Data Processing Engines (DPEs). To learn how pushdown works and when to use it, see SQL Pushdown Processing and SQL Pushdown for DQ Evaluation.
Prerequisites
Pushdown processing uses an operational database, that is, a dedicated dataset in BigQuery, where Ataccama caches lookup keys and stores intermediate results. Once you create the dataset, point the connection to it.
The operational database is required for DQ evaluation in pushdown.
For pushdown profiling, it’s optional: configure it to speed up profiling of views, SQL catalog items, and sliced sources. Ataccama then profiles a single cached copy instead of reading the source again for each group of columns. With on-demand pricing, creating the cached copy adds one scan of the source data, which BigQuery bills by bytes read. Profiling then reads the cached copy instead of running the view or query again. If the view or SQL catalog item filters, joins, or aggregates data, the cached copy is smaller than its source data, so the total cost can go down.
To create the dataset:
-
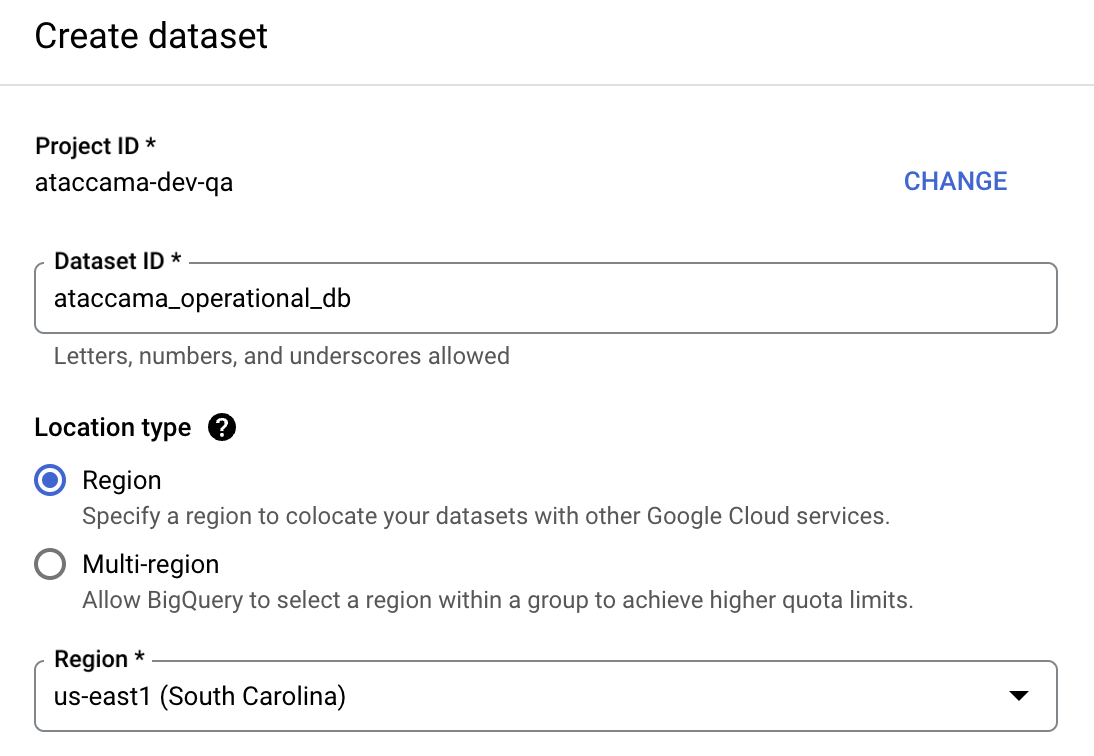
In BigQuery, select your project and using the three-dot menu, select Create dataset.
-
Provide the following:
-
Dataset ID: A unique name for the dataset.
-
Location type: Choose between Region and Multi-region and select your region. To learn more, see the official BigQuery documentation.
The region of this dataset must match the region of the dataset that contains the source data. 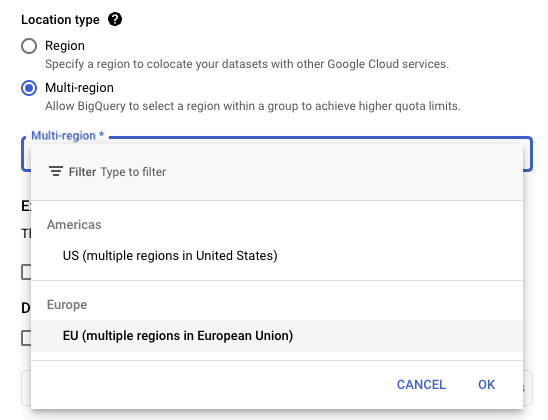
Leave the remaining fields at their defaults unless you need a custom configuration.
-
Use this dataset only for Ataccama processing data, not for data storage. Make sure the credentials configured on the connection can create, read, write, and delete tables in it.
Permissions for exporting invalid records
When exporting invalid records, ONE automatically creates the export table in BigQuery if not present. To enable this, the service account or user configured in your connection must have the following permissions, which are granted through IAM:
-- Create table on schema
GRANT `roles/bigquery.dataEditor` ON SCHEMA <project>.<dataset> TO '<principal>';

-- Insert and select on table
GRANT `roles/bigquery.dataEditor` ON TABLE <project>.<dataset>.<table> TO '<principal>';
Where:
-
<project>is the name of your BigQuery project (Project ID). -
<dataset>is the dataset where the invalid records table will be created. -
<table>is the name of the table used for storing invalid records. -
<principal>is the service account or user configured in your BigQuery connection credentials.
Enable pushdown profiling
Pushdown profiling is enabled on the connection level, either when adding a connection (see Add a connection) or when editing an existing one:
-
In the Pushdown processing section of the connection settings, enable Profile data using pushdown processing.
-
Choose whether you want to run term detection when pushdown processing is enabled, or disable term detection.
Term detection jobs can’t run in pushdown. See Term detection in pushdown.
-
Optionally, if you profile views, SQL catalog items, or sliced sources, configure the operational database. To determine whether you need one and for setup instructions, see Prerequisites. Otherwise, you can skip this step.
Enable pushdown for DQ evaluation
-
In the Pushdown processing section of the connection settings, enable Profile data using pushdown processing and Evaluate Data Quality using pushdown processing.
You can’t enable pushdown for DQ evaluation without first enabling pushdown profiling.
-
Provide the details of the dataset you created in BigQuery (see Prerequisites):
-
Project name: The name of your project in BigQuery (also known as
Project ID). This value is prefilled using information from the JDBC string provided in the connection.Enter a different name to override this value.
-
Dataset name: The name of the dataset you created in BigQuery.
Ataccama accesses the operational dataset with the credentials labeled as Operational on the connection. If there are none, the default credentials are used. For details, see Credentials.
-
Limitations of BigQuery pushdown
Because pushdown translates ONE expressions to BigQuery SQL and relies on native BigQuery support, the following limitations apply. For general pushdown limitations, see Limitations of pushdown processing.
JSON attributes and functions
JSON attributes in the data catalog and in pushdown DQ evaluation are supported only for BigQuery.
When expressions are evaluated in pushdown, BigQuery STRUCT and ARRAY values are converted to the JSON type.
Because BigQuery JSON stores numbers as INT64 or FLOAT64, numbers from the original structure can change.
A number that doesn’t fit either type becomes null.
A number that fits FLOAT64 but has more significant digits than it can hold loses precision.
The same applies to values parsed with json.parse.
The following limitations apply to JSON functions in pushdown:
-
Functions that modify JSON values are not supported:
json.set,json.remove,json.append, andjson.insert. -
arr.accumulateis not supported. -
arr.*functions work only on JSON arrays, not on arrays of primitive values. Inarr.map, the mapper must return a JSON value. If the result isn’t JSON by default, for example the output ofjson.get, wrap it injson.toJson:arr.map(array, (x) { json.toJson(json.toInteger(x) * 10) }) -
json.getandjson.existsaccept only constant paths. -
str.jsonParseis not supported because BigQuery has no lenient JSON parser. Usejson.parseinstead, which parses in strict mode and can still behave differently from local evaluation. -
Lambda function bodies cannot contain aggregate functions.
-
toStringalways produces valid JSON, but object fields can be ordered differently and values serialized differently than in local evaluation. -
Functions that compare JSON values, such as
arr.contains,arr.indexOf,arr.sort, andarr.distinct, compare the serialized form. Results can therefore differ between pushdown and local evaluation. Use the lambda variants of these functions to supply a custom comparison or a non-JSON sort key.
For the full function reference, see JSON functions.
Add credentials
Different sets of credentials can be used for different tasks. One set of credentials must be set as default for each connection.
To determine whether you need to configure more than a single set of credentials, see Connection credentials.
-
Select Add Credentials.
-
Choose an authentication method and proceed with the corresponding step:
Integrated credentials
-
Provide the following:
-
Name (Optional): A name for this set of credentials.
-
Description (Optional): A description for this set of credentials.
-
-
If you want to use this set of credentials by default when connecting to the data source, select Set as default.
See also Connection credentials.
-
Proceed with Test the connection.
If you select integrated credentials you need to provide OAuthPvtKeyPath via driver properties.
-
Select Add Driver property.
-
Property name:
OAuthPvtKeyPath. -
Driver property type:
File. -
Content: Browse and upload your service account key file (.json or .p12 format).
-
OAuth Google user credentials
-
Select OAuth Google user credentials and provide the following:
-
Name (Optional): A name for this set of credentials.
-
Description (Optional): A description for this set of credentials.
-
Select a secret management service (optional): If you want to use a secret management service to provide values for the following fields, specify which secret management service should be used. After you select the service, you can enable the Use secret management service toggle and provide instead the names the values are stored under in your key vault. For more information, see Secret Management Service.
-
Client ID: The OAuth 2.0 client ID.
-
Client secret: The OAuth 2.0 client secret. Alternatively, enable Use secret management service and provide the name this value is stored under in your selected secret management service.
-
-
If you want to use this set of credentials by default when connecting to the data source, select Set as default.
See also Connection credentials.
OAuth Google user JDBC
Connect to the server using a connection URL written in the following format:
jdbc:bigquery://<Host>:<Port>;ProjectId=<Project>;The variables are defined as follows:
-
<Host>is the DNS or IP address of the server. -
<Port>is the number of the TCP port to connect to. Specifying the port number is optional if you are connecting to port 443. -
<Project>is the name of your BigQuery project.
jdbc:bigquery://https://www.googleapis.com/bigquery/v2:443;ProjectId=MyProject;The connector opens a new browser window to Google sign-in page. Sign in using the new browser window and the connector obtains the refresh token.
Google service account key credentials
-
Select Google service account key credentials and provide the following:
-
Name (Optional): A name for this set of credentials.
-
Description (Optional): A description for this set of credentials.
-
Service account key: Upload the service account key (in JSON file format) associated with the project where the Google Cloud Storage bucket you want to connect to is located.
To learn how to create a service account and obtain the service account key from your Google Cloud project, see the official Google documentation:
-
-
If you want to use this set of credentials by default when connecting to the data source, select Set as default.
See also Connection credentials.
Google service account key JDBC
Connect to the server using a connection URL written in the following format:
jdbc:bigquery://<Host>:<Port>;ProjectId=<Project>;OAuthServiceAcctEmail=<ServiceAccountEmail>;The variables are defined as follows:
-
<Host>is the DNS or IP address of the server. -
<Port>is the number of the TCP port to connect to. Specifying the port number is optional if you are connecting to port 443. -
<Project>is the name of your BigQuery project. -
<ServiceAccountEmail>is the service account email address for authentication.
jdbc:bigquery://https://www.googleapis.com/bigquery/v2:443;ProjectId=MyProject;OAuthServiceAcctEmail=my-service-account@my-project.iam.gserviceaccount.com;The connector uses the service account to authenticate the connection.
Test the connection
To test and verify whether the data source connection has been correctly configured, select Test Connection.
If the connection is successful, continue with the following step. Otherwise, verify that your configuration is correct and that the data source is running.
Save and publish
Once you have configured your connection, save and publish your changes. If you provided all the required information, the connection is now available for other users in the application.
In case your configuration is missing required fields, you can view a list of detected errors instead. Review your configuration and resolve the issues before continuing.
Next steps
You can now browse and profile assets from your connection.
In Data Catalog > Sources, find and open the source you just configured. Switch to the Connections tab and select Document. Alternatively, opt for Import or Discover documentation flow.
Or, to import or profile only some assets, select Browse on the Connections tab. Choose the assets you want to analyze and then the appropriate profiling option.
Was this page useful?