
Snowflake Connection
This article describes how to connect to Snowflake.
Create a source
To connect to Snowflake:
-
Navigate to Data Catalog > Sources.
-
Select Create.
-
Provide the following:
-
Name: The source name.
-
Description: A description of the source.
-
Deployment (Optional): Choose the deployment type.
You can add new values if needed. See Lists of Values.
-
Stewardship: The source owner and roles. For more information, see Stewardship.
-
| Alternatively, add a connection to an existing data source. See Connect to a Source. |
Add a connection
-
Select Add Connection.
-
In Select connection type, choose Relational Database > Snowflake.
-
Provide the following:
-
Name: A meaningful name for your connection. This is used to indicate the location of catalog items.
-
Description (Optional): A short description of the connection.
-
Dpe label (Optional): Assign the processing of a data source to a particular data processing engine (DPE) by entering the DPE label assigned to the engine. For more information, see DPM and DPE Configuration in DPM Admin Console.
-
Override catalog item name: Select this option if you want metadata imports to overwrite the names of existing catalog items with the latest names from the data source.
If the option is not selected, catalog item names you set in ONE are preserved when metadata is reimported. See Edit catalog item metadata.
-
JDBC: A JDBC connection string pointing to the IP address or the URL where the data source can be reached. For a list of supported sources and JDBC drivers, see Supported Data Sources.
Depending on the data source and the authentication method used, additional properties might be required for successful connection. See Add Driver Properties.
-
-
In the Pushdown processing section, optionally enable pushdown processing to run profiling and DQ evaluation directly in Snowflake. See Pushdown processing.
-
In Additional settings:
-
Select Enable exporting and loading of data if you want to export data from this connection and use it in ONE Data or outside of ONE.
If you want to export data to this source, you also need to configure write credentials. See Connection credentials.
Consider the security and privacy risks of allowing the export of data to other locations. -
Select Enable analytical queries if you want to create data visualizations in Data Stories based on catalog items from this connection.
-
Pushdown processing
Pushdown processing lets you run profiling, DQ evaluation, monitoring projects, and data observability jobs (excluding term detection and AI-powered anomaly detection) directly in Snowflake instead of on Ataccama Data Processing Engines (DPEs). To learn how pushdown works and when to use it, see SQL Pushdown Processing and SQL Pushdown for DQ Evaluation.
Pushdown uses your Snowflake warehouse for computation, giving you easy control of the resources used. When you profile a view or an SQL catalog item with many columns, Ataccama first copies it into a cache table and profiles the copy. See How pushdown profiling works.
Snowflake pushdown has two implementations, controlled by the Legacy pushdown setting on the connection. This section describes the current implementation, with Legacy pushdown turned off.
Legacy pushdown is the older implementation: keep it turned off unless your DQ rules rely on functions that are supported only there. See Snowflake Legacy Pushdown.
Prerequisites
Before you enable pushdown processing:
-
Make sure your Snowflake warehouse is sized for the workload, as its size determines the processing performance. With a small warehouse, processing can be slow.
-
Check that the DQ rules applied to catalog items and in monitoring projects on this connection are supported in pushdown. See Verify rule support and Supported functions and operators.
-
If you use pushdown for DQ evaluation, create a working database and schema in Snowflake, and make sure the credentials on the connection can create, read, write, and delete tables in it.
-
If you want to export invalid records from monitoring projects, grant the required permissions in Snowflake. See Permissions for exporting invalid records.
Permissions for exporting invalid records
Invalid records export is available only with Legacy pushdown turned off.
When exporting invalid records, Ataccama ONE automatically creates the export table in Snowflake if not present.
To enable this, the Snowflake role configured in your connection credentials must have the following permissions:
-- Grant database and schema access
GRANT USAGE ON DATABASE <database> TO ROLE <role>;
GRANT USAGE ON SCHEMA <database>.<schema> TO ROLE <role>;
-- Grant INSERT and DELETE privileges on the table
GRANT INSERT, DELETE ON TABLE <database>.<schema>.<table> TO ROLE <role>;
-- (Optional) Grant SELECT privilege on the table
GRANT SELECT ON TABLE <database>.<schema>.<table> TO ROLE <role>;
-- Allow users to create tables in the schema
GRANT CREATE TABLE ON SCHEMA <database>.<schema> TO ROLE <role>;
Where:
-
<database>is the Snowflake database where the invalid records table is stored. -
<schema>is the schema where the invalid records table exists or will be created. -
<table>is the name of the table used for storing invalid records. -
<role>is the Snowflake role configured in your connection credentials.
Enable pushdown processing
Pushdown processing is enabled on the connection level, either when adding a connection (see Add a connection) or on an existing connection:
-
In Knowledge Catalog > Sources, select your Snowflake source.
-
Select the Connections tab.
-
For the required connection, use the three-dot menu and select Edit.
-
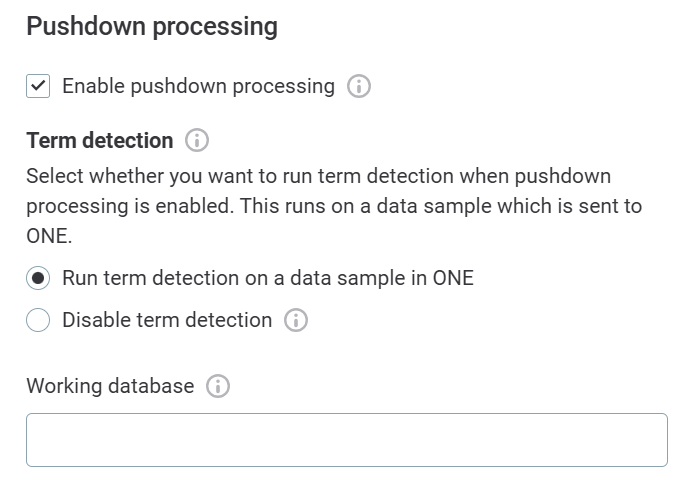
In the Pushdown processing section, select Enable pushdown processing.
-
Leave Legacy pushdown turned off. If your DQ rules depend on functions that are supported only in the legacy implementation, see Snowflake Legacy Pushdown.
-
In Working database and Working schema, enter the database and schema where Ataccama can store lookups and intermediate results. The working database is required for DQ evaluation. If you only use pushdown for profiling, it’s optional: if you configure it, profiling caches data in it, otherwise in temporary tables. See How pushdown profiling works.
-
Choose whether you want to run term detection when pushdown processing is enabled, or disable term detection.
Term detection jobs can’t run in pushdown. See Term detection in pushdown.
-
Select Add JDBC role to add a JDBC role if you need to share the Snowflake pushdown setting across different credentials (for example, to a common underlying role).
Limitations of Snowflake pushdown
Because pushdown translates ONE expressions to Snowflake SQL and relies on native Snowflake support, the following limitations apply:
-
Rules that use custom functions are currently reported as not supported in pushdown and are skipped during evaluation.
-
Supported regular expressions and patterns match those Snowflake supports, which is most of the POSIX ERE syntax. See String functions (regular expressions) in the Snowflake documentation.
-
Some functions are supported only with restrictions, for example,
eraseSpacesInNames. See Source-specific notes. -
For general pushdown limitations, see Limitations of pushdown processing.
Geospatial functions
-
Geospatial functions work on values of the
GEOGRAPHYnative type or on text representations of the same meaning. For supported text formats, see Snowflake documentation. -
On values of
GEOMETRYtype, geospatial functions might run but return different results. -
The text-to-
GEOGRAPHYconversion relies on Snowflake support, which might produce runtime errors and incurs a performance penalty.
Add credentials
Different sets of credentials can be used for different tasks. One set of credentials must be set as default for each connection.
To determine whether you need to configure more than a single set of credentials, see Connection credentials.
-
Select Add Credentials.
-
Choose an authentication method and proceed with the corresponding step:
-
Username and password: Basic authentication using your username and a password.
-
Key-pair authentication: Enhanced security authentication as an alternative to username and password authentication.
-
OAuth credentials: Use OAuth 2.0 tokens to provide secure delegated access.
-
OAuth user SSO credentials: Use an external identity provider Single Sign-On (SSO).
-
| These sections include references to Azure AD, which you might also know as Microsoft Entra ID. |
Username and password
-
Select Username and password.
-
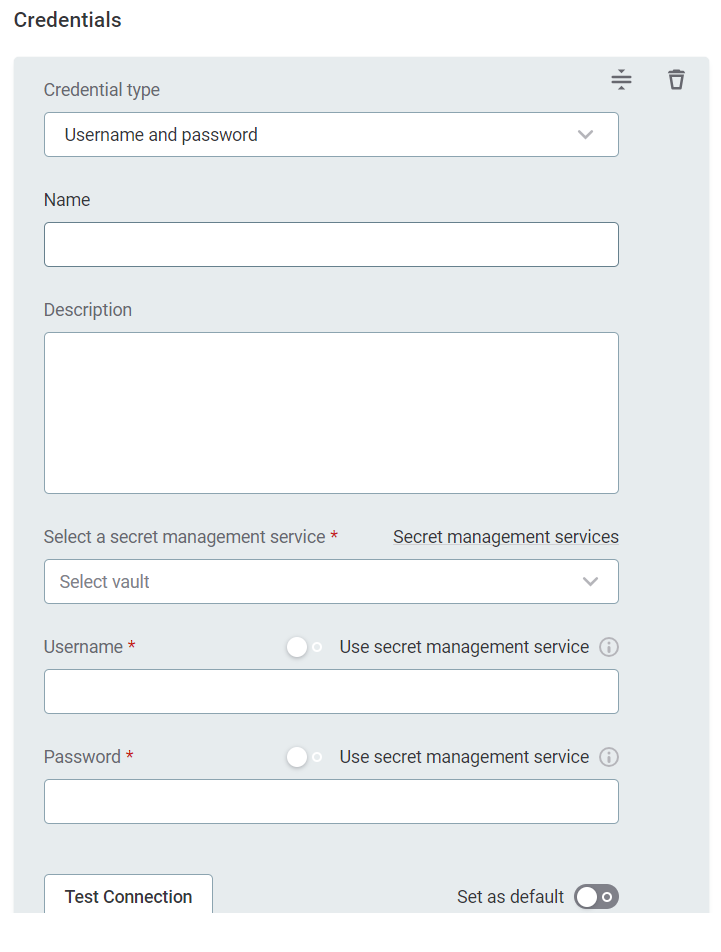
Provide the following:
-
Name (Optional): A name for this set of credentials.
-
Description (Optional): A description for this set of credentials.
-
Select a secret management service (optional): If you want to use a secret management service to provide values for the following fields, specify which secret management service should be used. After you select the service, you can enable the Use secret management service toggle and provide instead the names the values are stored under in your key vault. For more information, see Secret Management Service.
-
Username: The username for the data source. Alternatively, enable Use secret management service and provide the name this value is stored under in your selected secret management service.
-
Password: The password for the data source. Alternatively, enable Use secret management service and provide the name this value is stored under in your selected secret management service.
-
-
If you want to use this set of credentials by default when connecting to the data source, select Set as default.
See also Connection credentials.
-
Proceed with Test the connection.
| Snowflake’s “secure by default” policy means that password-only authentication is not supported for new accounts (from September 30th, 2024): key-pair authentication is required, as per the official Snowflake documentation. Proceed to Key-pair authentication. |
Key-pair authentication
Before configuring key-pair authentication, you need to generate a key pair and configure it in Snowflake.
Prerequisites: Generate and configure keys
-
Generate your private key using the openssl tool:
openssl genrsa 2048 | openssl pkcs8 -topk8 -v1 PBE-SHA1-3DES -inform PEM -out rsa_key.p8When prompted, provide a password of your choosing.
-
Extract the public key from your private key:
openssl rsa -in rsa_key.p8 -pubout -out rsa_key.pubEnter the password you created in the previous step.
-
Configure the public key in Snowflake:
-
Go to Worksheets and run the following SQL command. You must run this command from the
ACCOUNTADMINrole or another role with appropriate privileges. Replace<user>with the actual Snowflake username, and<public key value>with the content of yourrsa_key.pubfile without the header and footer lines, as a single line of characters.ALTER USER <user> SET RSA_PUBLIC_KEY = '<public key value>'Alternatively, you can set the public key through the UI: go to Admin → Users & Roles → Users → Select user → Edit → Advanced → RSA Public Key.
-
Configure the connection
-
Select Username and password.
-
In Username, add the username associated with your Snowflake database. This should be the same user you configured in the prerequisites, that is, in the
ALTER USERcommand in step 3. -
In Password, enter any value. While the password isn’t used for key-pair authentication, the field cannot be left empty.
-
Use Add Driver property to add the private key file:
-
Driver property name:
private_key_file -
Driver property type:
File -
Encrypted: True
-
In Content, upload your
rsa_key.p8file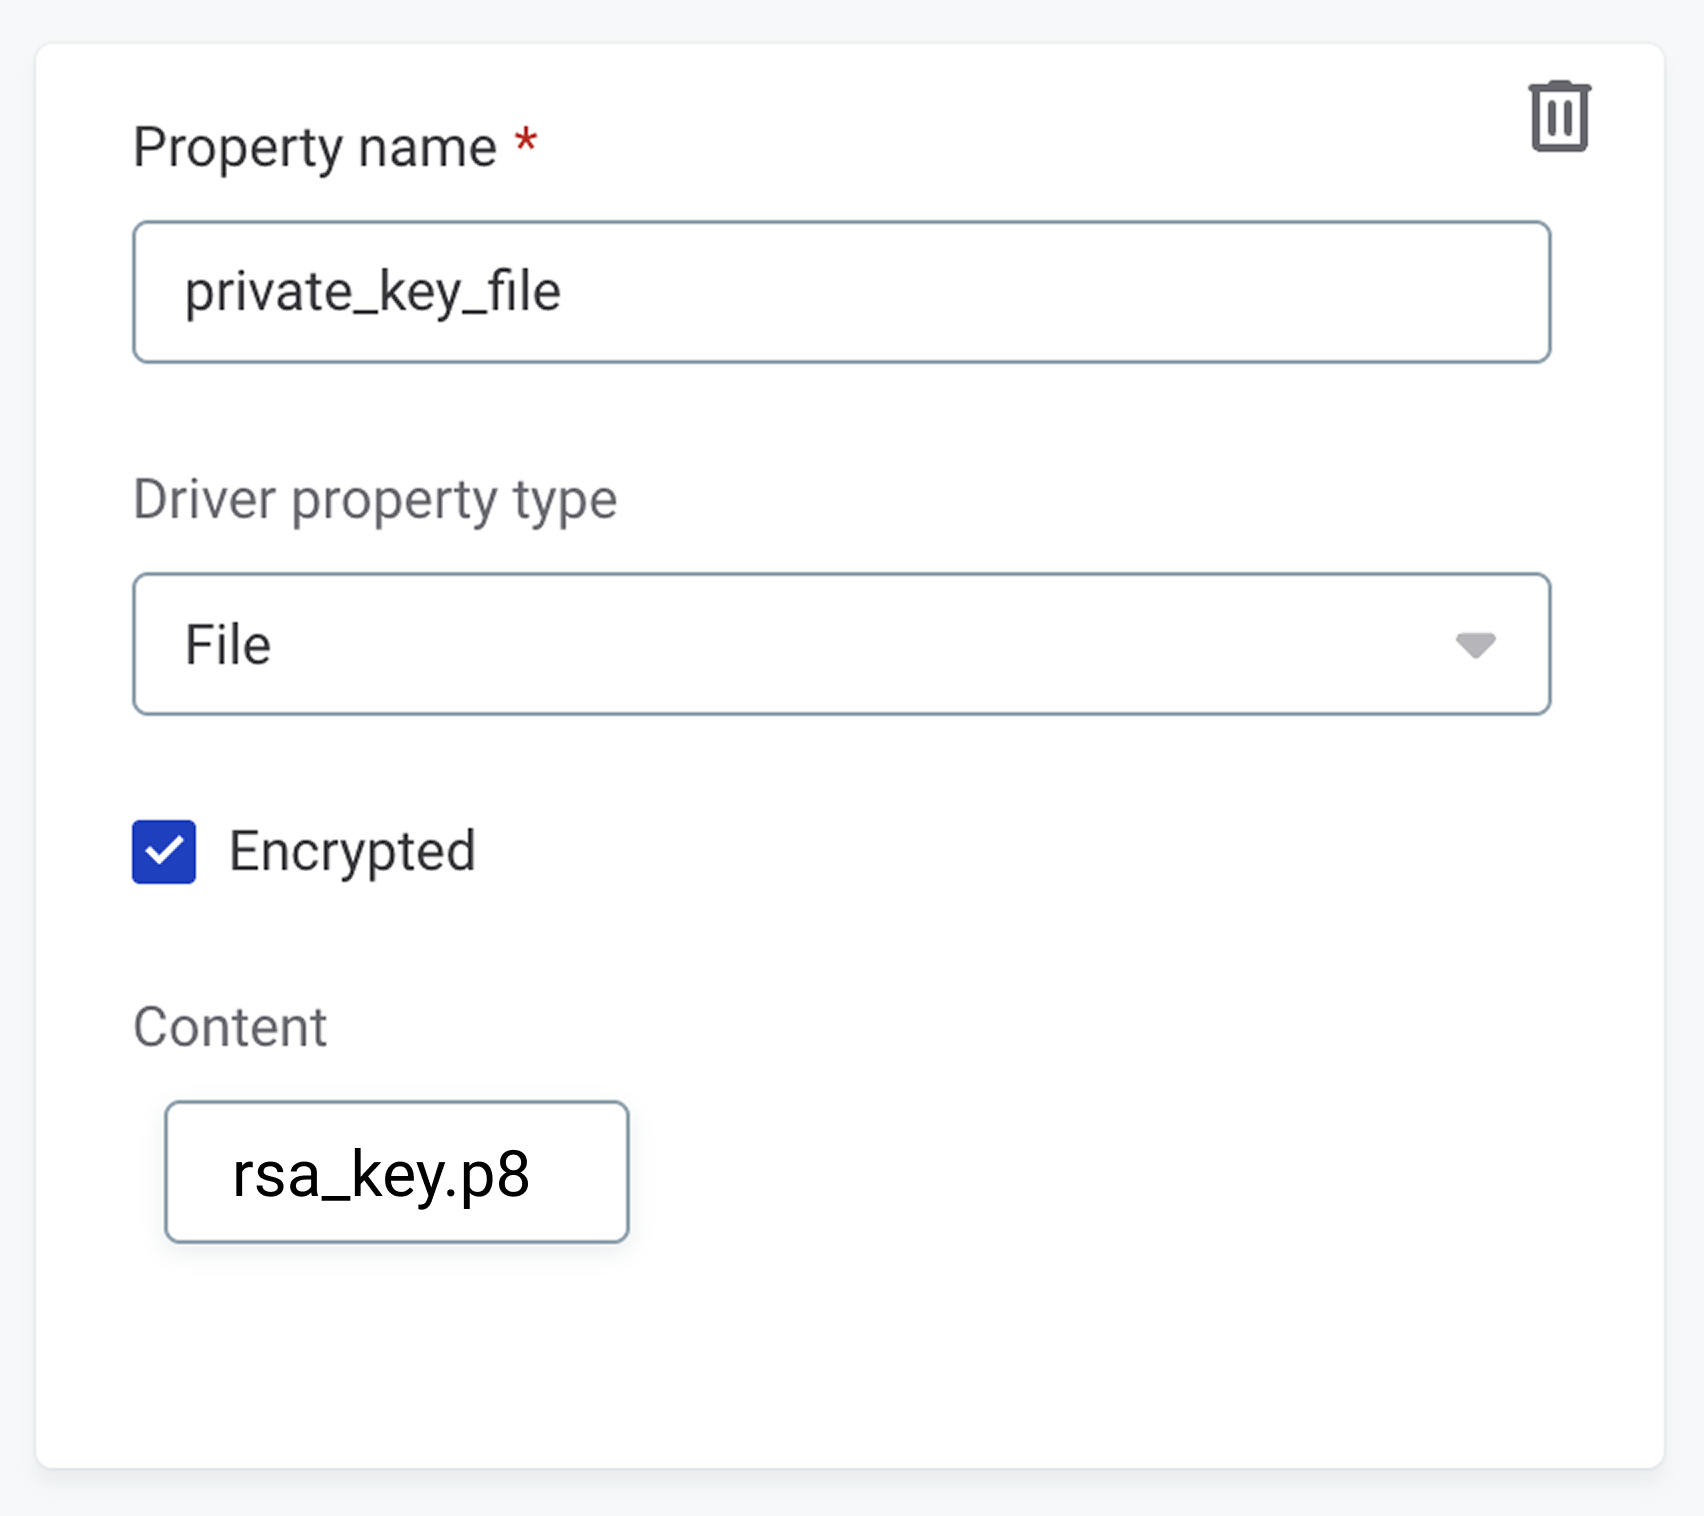
-
-
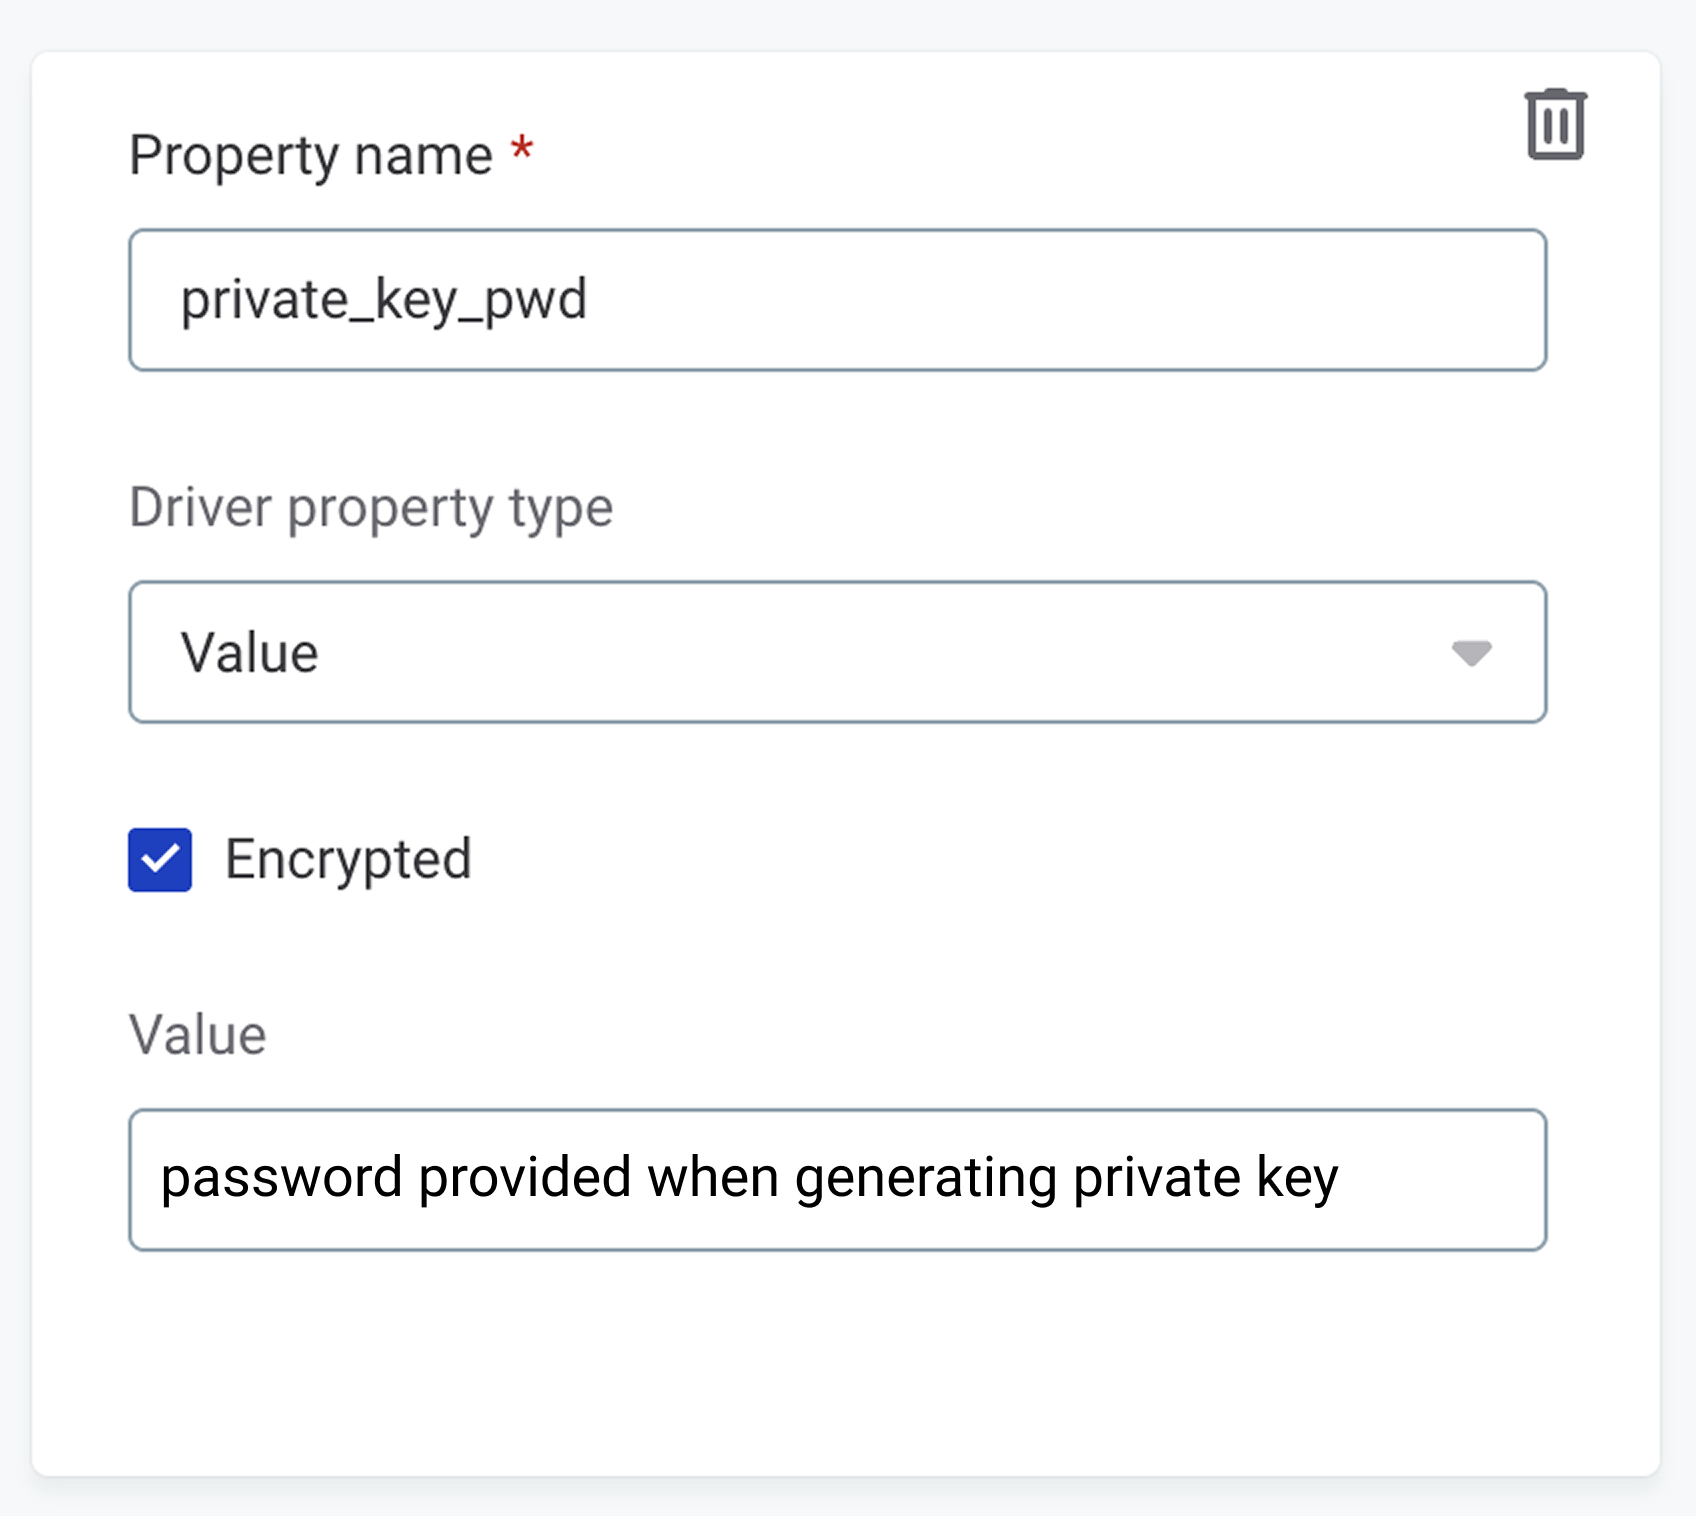
Use Add Driver property to add the private key password:
-
Driver property name:
private_key_pwd -
Driver property type:
Value -
Encrypted: True
-
In Value, provide the password you used when generating the private key
-
Key-pair authentication with JWT authenticator
This method uses Snowflake’s JWT authenticator with key-pair authentication. It follows the same principle as standard key-pair authentication but explicitly specifies the JWT authenticator in the driver properties.
Prerequisites: Generate and configure keys
Follow the same key generation and configuration steps as described in the Key-pair authentication section.
Configure the connection
-
Select Username and password.
-
Provide the following:
-
Name (Optional): A name for this set of credentials.
-
Description (Optional): A description for this set of credentials.
-
Username: The username for the data source. This should be the same user you configured with the public key in Snowflake, that is, in the
ALTER USERcommand in step 3 of the prerequisites. -
Password: Enter any value. While the password isn’t used to connect to Snowflake, the credentials cannot be saved if the field is left empty.
-
-
Use Add Driver property to add the authenticator:
-
Driver property name:
authenticator -
Driver property type:
Value -
Value:
snowflake_jwt
-
-
Use Add Driver property to add the private key file:
-
Driver property name:
private_key_file -
Driver property type:
File -
Encrypted: Select this option
-
In Content, upload your private key
-
Alternatively, you can set the authenticator as a parameter in the JDBC connection string when setting up the connection.
For example: &authenticator=snowflake_jwt.
If you encounter the error Test connection has failed: Private key provided is invalid or not supported, see Troubleshooting.
OAuth credentials
If you are using OAuth 2.0 tokens, you also need to supply the Redirect URL to the data source you’re connecting to. This information is available when configuring the connection.
Note that only OAuth flows where the programmatic client acts on behalf of a user are supported. If your programmatic client is configured to request an access token for itself, the connection will fail. For details, see the Configure Microsoft Entra ID for External OAuth article in the Snowflake official documentation, specifically steps 10 and 11.
-
Select OAuth Credentials.
-
Provide the following:
-
Name (Optional): A name for this set of credentials.
-
Description (Optional): A description for this set of credentials.
-
Select a secret management service (optional): If you want to use a secret management service to provide values for the following fields, specify which secret management service should be used. After you select the service, you can enable the Use secret management service toggle and provide instead the names the values are stored under in your key vault. For more information, see Secret Management Service.
-
Redirect URL: This field is predefined and read-only. This URL is required to receive the refresh token and must be provided to the data source you’re integrating with.
-
Client ID: The OAuth 2.0 client ID.
-
Client secret: The client secret used to authenticate to the authorization server. Alternatively, enable Use secret management service and provide the name this value is stored under in your selected secret management service.
-
Authorization endpoint: The OAuth 2.0 authorization endpoint of the data source. It is required only if you need to generate a new refresh token.
-
Token endpoint: The OAuth 2.0 token endpoint of the data source. Used to get access to a token or a refresh token.
-
Refresh token: The OAuth 2.0 refresh token. Allows the application to authenticate after the access token has expired without having to prompt the user for credentials.
Select Generate to create a new token. Once you do this, the expiration date of the refresh token is updated in Refresh token valid till.
-
-
If you want to use this set of credentials by default when connecting to the data source, select Set as default.
See also Connection credentials.
-
Proceed with Test the connection.
OAuth user SSO credentials
Authenticating through an external identity provider SSO involves users logging into ONE through an external OIDC identity provider (for example, Okta) and using their identity when accessing a data source.
As a prerequisite, you need to set up the integration with the external identity provider. See Okta OIDC Integration with Impersonation.
-
Provide the following:
-
Name (Optional): A name for this set of credentials.
-
Description (Optional): A description for this set of credentials.
-
-
If you want to use this set of credentials by default when connecting to the data source, select Set as default.
See also Connection credentials.
-
Proceed with Test the connection.
Azure AD Service Principal via driver properties
Snowflake on Azure can be integrated with Azure AD for authentication.
-
Select Integrated credentials and provide the following:
-
Name (Optional): A name for this set of credentials.
-
Description (Optional): A description for this set of credentials.
-
-
If you want to use this set of credentials by default when connecting to the data source, select Set as default.
See also Connection credentials.
-
Use Add Driver property to add the following driver properties:
Driver property name Driver property type Encrypted Value Content authenticatorValue
False
OAUTHn/a
tokenValue
False
SECRET:your-secret-namen/a
ata.jdbc.aad.authTypeValue
False
AAD_CLIENT_CREDENTIALn/a
ata.jdbc.aad.tenantUrlValue
False
login.microsoftonline.com/<your-tenant-id>/oauth2/v2.0/tokenn/a
ata.jdbc.aad.tenantIdValue
False
<tenant ID of your subscription (UUID format)>n/a
ata.jdbc.aad.clientIdValue
False
<service principal client ID (UUID format)>n/a
ata.jdbc.aad.clientSecretValue
True
<service principal client secret>n/a
ata.jdbc.aad.resourceValue
False
<resource ID>.ata.jdbc.aad.resourceis the Resource ID of Snowflake in Azure and takes the following form (GUID),ab12c456-789d-01ef-gg22-3h44i5jkl67mn/a
-
Proceed with Test the connection.
Test the connection
To test and verify whether the data source connection has been correctly configured, select Test Connection.
If the connection is successful, continue with the following step. Otherwise, verify that your configuration is correct and that the data source is running.
Save and publish
Once you have configured your connection, save and publish your changes. If you provided all the required information, the connection is now available for other users in the application.
In case your configuration is missing required fields, you can view a list of detected errors instead. Review your configuration and resolve the issues before continuing.
Next steps
You can now browse and profile assets from your connection.
In Data Catalog > Sources, find and open the source you just configured. Switch to the Connections tab and select Document. Alternatively, opt for Import or Discover documentation flow.
Or, to import or profile only some assets, select Browse on the Connections tab. Choose the assets you want to analyze and then the appropriate profiling option.
Troubleshooting
Test connection has failed: Private key provided is invalid or not supported
If you are seeing this error, it could be because the key was generated using OpenSSL V3. A possible solution is adding the following property to the Snowflake JDBC driver in DPE.
Try adding the following parameter to DPE Start script /etc/systemd/system/dpe.service.d/dpe.conf and testing the connection again:
Environment="JAVA_OPTS=[...] -Dnet.snowflake.jdbc.enableBouncyCastle=true"Error when browsing Snowflake data source
If an error is being thrown, or the application is unresponsive when you try to browse your Snowflake data source, the Snowflake warehouse might be overloaded.
By default, Ataccama uses the Snowflake warehouse specified in the JDBC connection string both for browsing and processing. A single Snowflake warehouse can run up to eight concurrent SQL queries: if you run multiple Snowflake processing in parallel, it might lead to DPE overloading the warehouse with the concurrent queries. If this happens, ONE can’t run interactive queries, such as data source browsing, data preview, or metadata import, until the processing jobs finish.
A couple of different error messages can be shown in this event, two examples are:
-
Test connection has failed: DPE is not available.
-
DEADLINE_EXCEEDED.
To overcome this limitation, you can create a separate Snowflake warehouse of XS size and specify it in the driver properties. This warehouse can then be used for the interactive capabilities, while the job processing will be done by the warehouse specified in the connection string.
To do this, add the property browsingWarehouseOverride to your Snowflake connection, as follows:
-
In Sources, select your Snowflake data source.
-
Navigate to the Connections tab.
-
On the connection for which you want to add the property, use the three-dot menu and select Show details.
-
You are now on the Overview tab for that connection. In the Driver properties section, select Add Driver Property and add the following details:
-
Property name:
browsingWarehouseOverride. -
Driver property type: Value.
-
Value: The name of your XS Snowflake warehouse.
This warehouse needs to be created beforehand in Snowflake.
-
Pushdown processing fails with message Processing aborted due to error 300010:2765523699
Snowflake pushdown processing fails with the following error: Processing aborted due to error 300010:2765523699; incident [incident_number].
This issue has to do with internal Snowflake processing and typically occurs when the table contains a column of type MAP(STRING, OBJECT).
Some other complex object types might also result in the same error.
Such columns cannot be detected in advance as all MAP and OBJECT types are reported as the general OBJECT type.
As a workaround, the following options are available:
-
Process the table in DPE instead of using pushdown processing.
-
Exclude all
OBJECTtypes from pushdown processing.To do this, set the JDBC driver property
ata.pushdown.ignore.object.typetotrueand remove any DQ rules from columns ofOBJECTtype. With this setting, only non-OBJECTtypes are processed.The property is configured on the source connection. For details, see Add Driver Properties.
Was this page useful?